How DoorDash knew its AI agent got worse
DoorDash had a production agent running on Claude Sonnet 4.6.
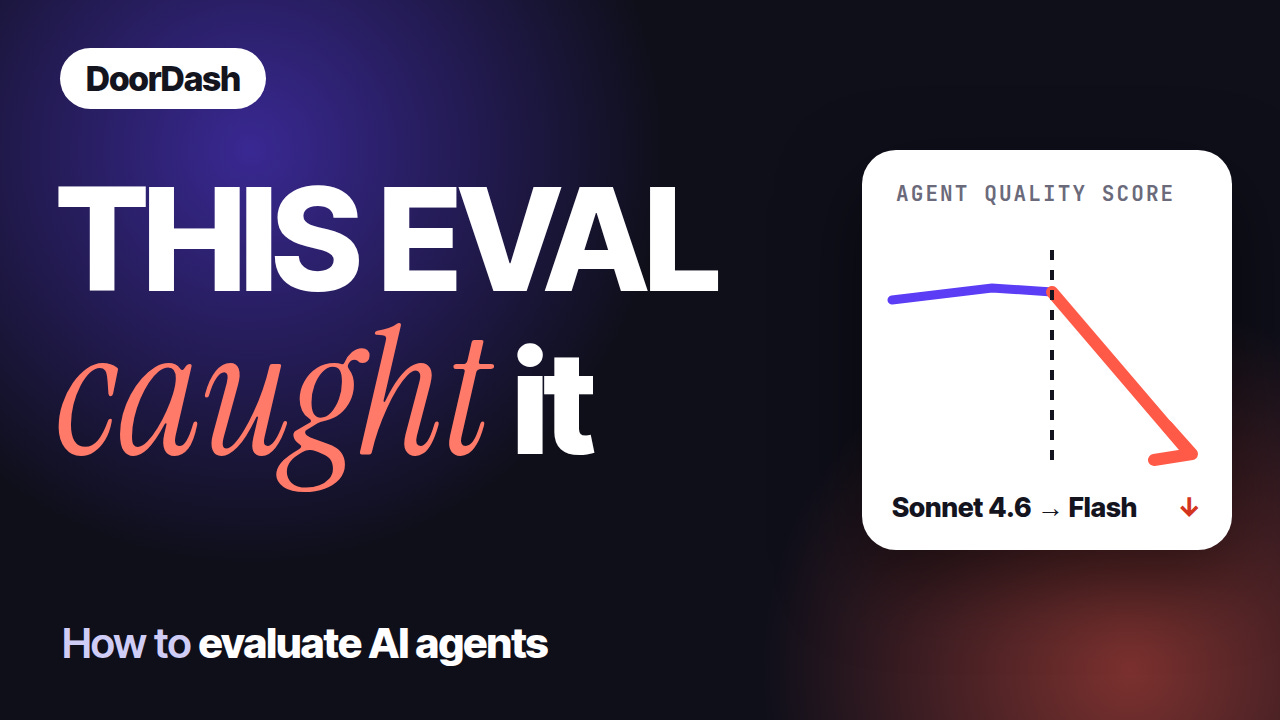
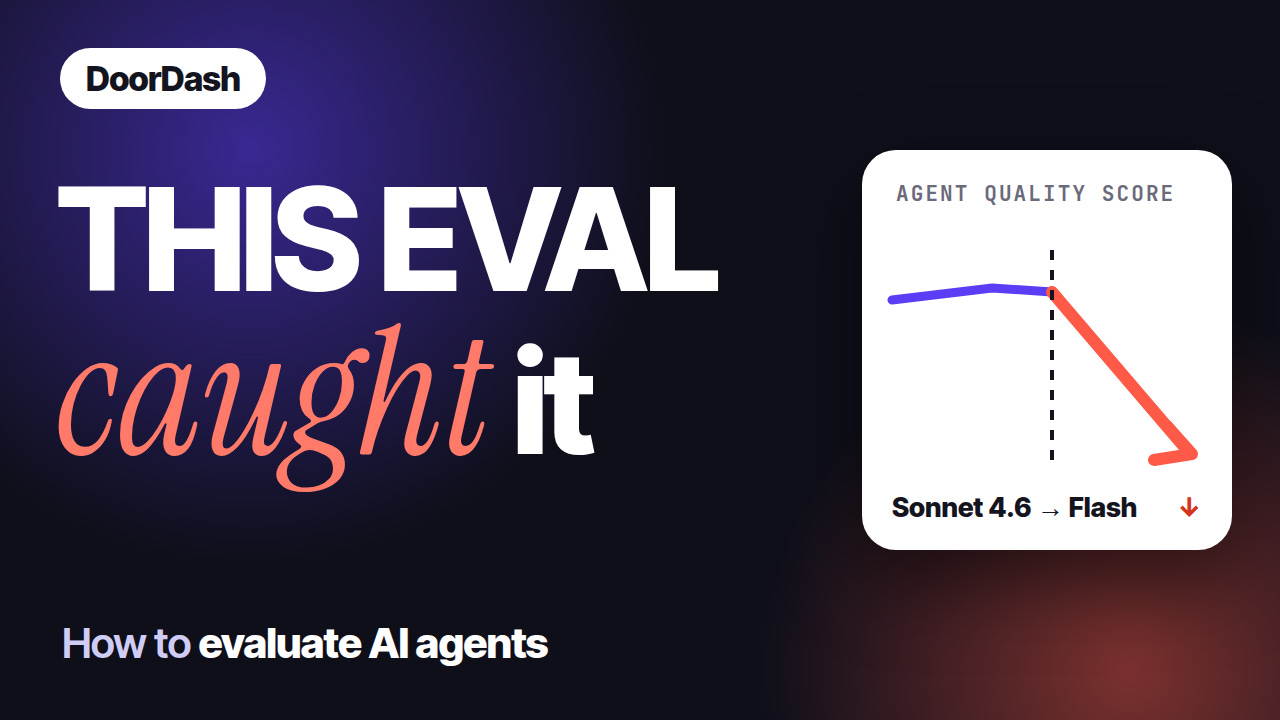
DoorDash had a production agent running on Claude Sonnet 4.6. Then Gemini 3.5 Flash shipped with lower latency on the table. DoorDash says its offline evals showed the scores dropped sharply.
It wasn’t a capability gap. It was a compatibility gap. The system prompt and the tool layer had been tuned around Sonnet, and DoorDash only found that out because of the eval harness it had built.
Here is how that harness works, and what I learned rebuilding a small version.
Why agents are hard to grade
Two problems, per DoorDash:
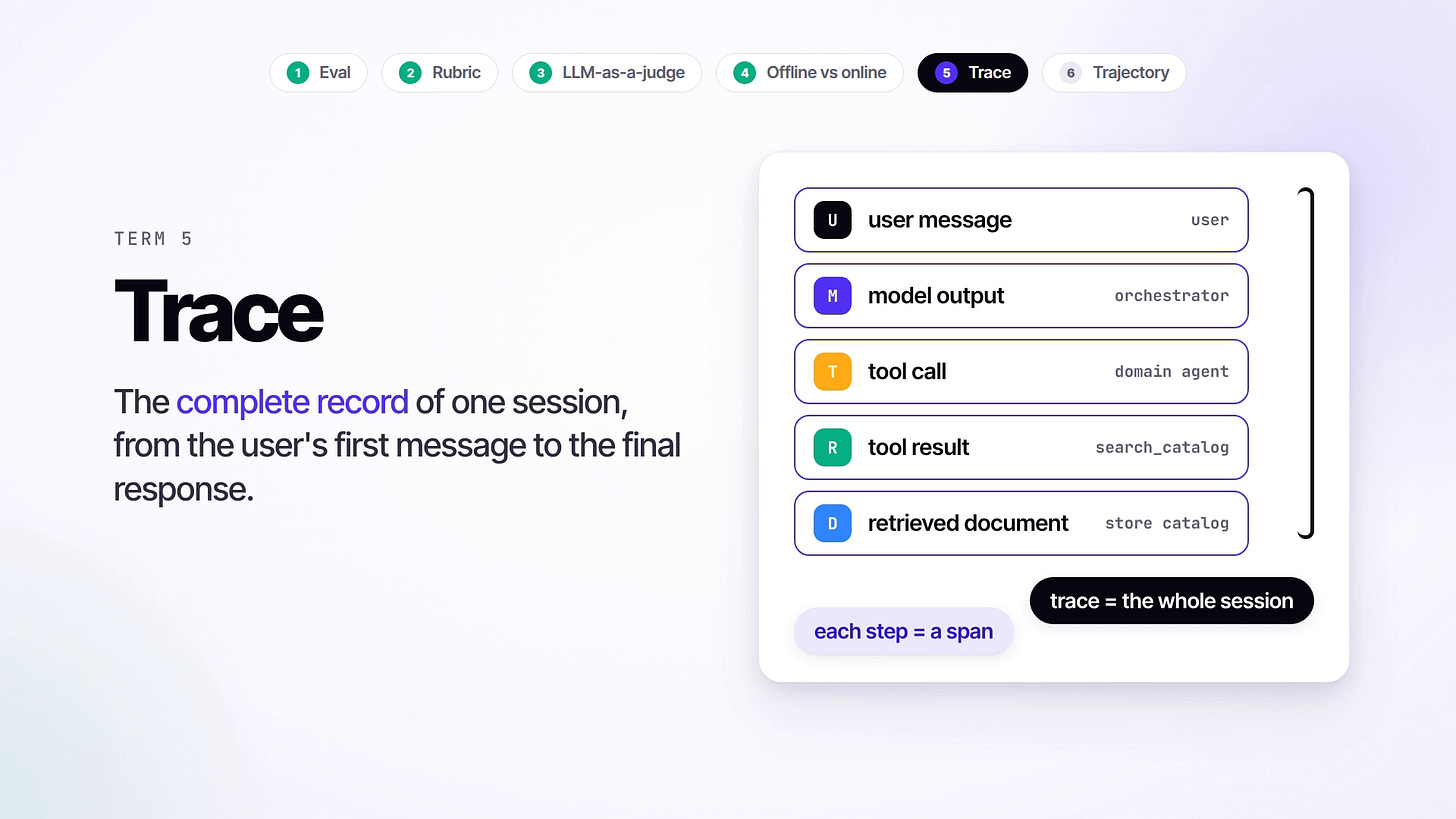
- A final answer isn’t enough. The real work happens in tool calls the user never sees, so you grade the whole trace (the complete record of one session), not just the last message.
- There’s no safe rehearsal. You can’t test a change on real users, and you can’t replay a past session against a modified agent.
The harness, in four parts
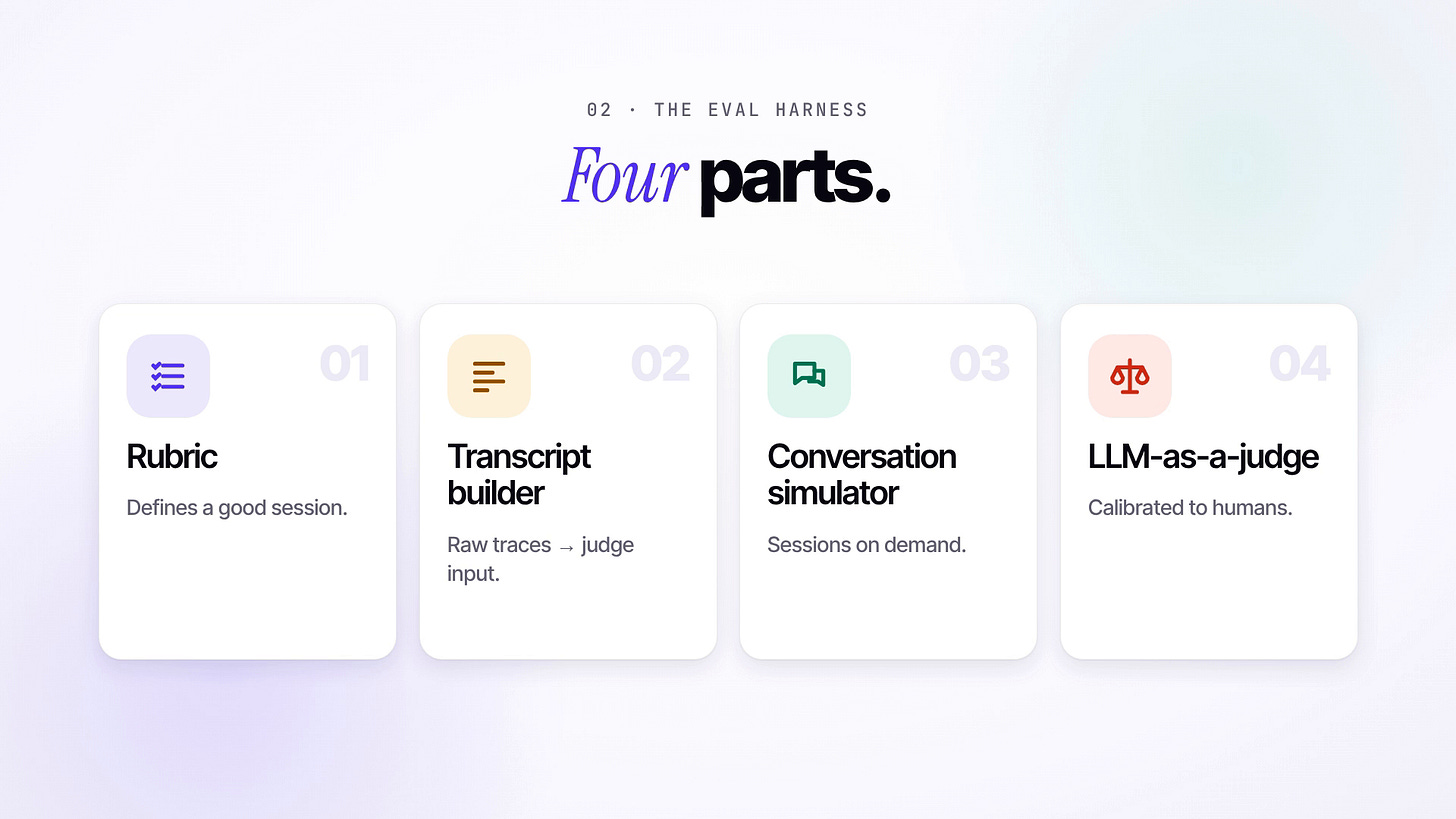
- Rubric: binary pass/fail criteria. Each has an eligibility step, so a recipe flow isn’t marked down for missing a reorder step.
- Transcript builder: turns a raw trace into something a judge can read, and gives each criterion only the evidence it needs.
- Conversation simulator: an LLM plays the shopper. Recorded tool payloads (fixtures) freeze the environment, and eight trials per scenario show the real pass rate instead of one lucky run.
- LLM-as-a-judge: one verdict per criterion, calibrated against human labels on a held-out set.
DoorDash’s one caution applies to you too: it doesn’t publish judge-human agreement numbers, so don’t assume your judge is calibrated. Measure it.
I built a mini version
doordash-eval-harness: 49 lines of core code, six scenarios, and a table that tells you which model broke which rule.
I ran GPT-5 and GPT-5 mini, eight trials per scenario. Headline: 71% against 67%, but the confidence intervals overlap, so that’s not a winner. The columns are the story:
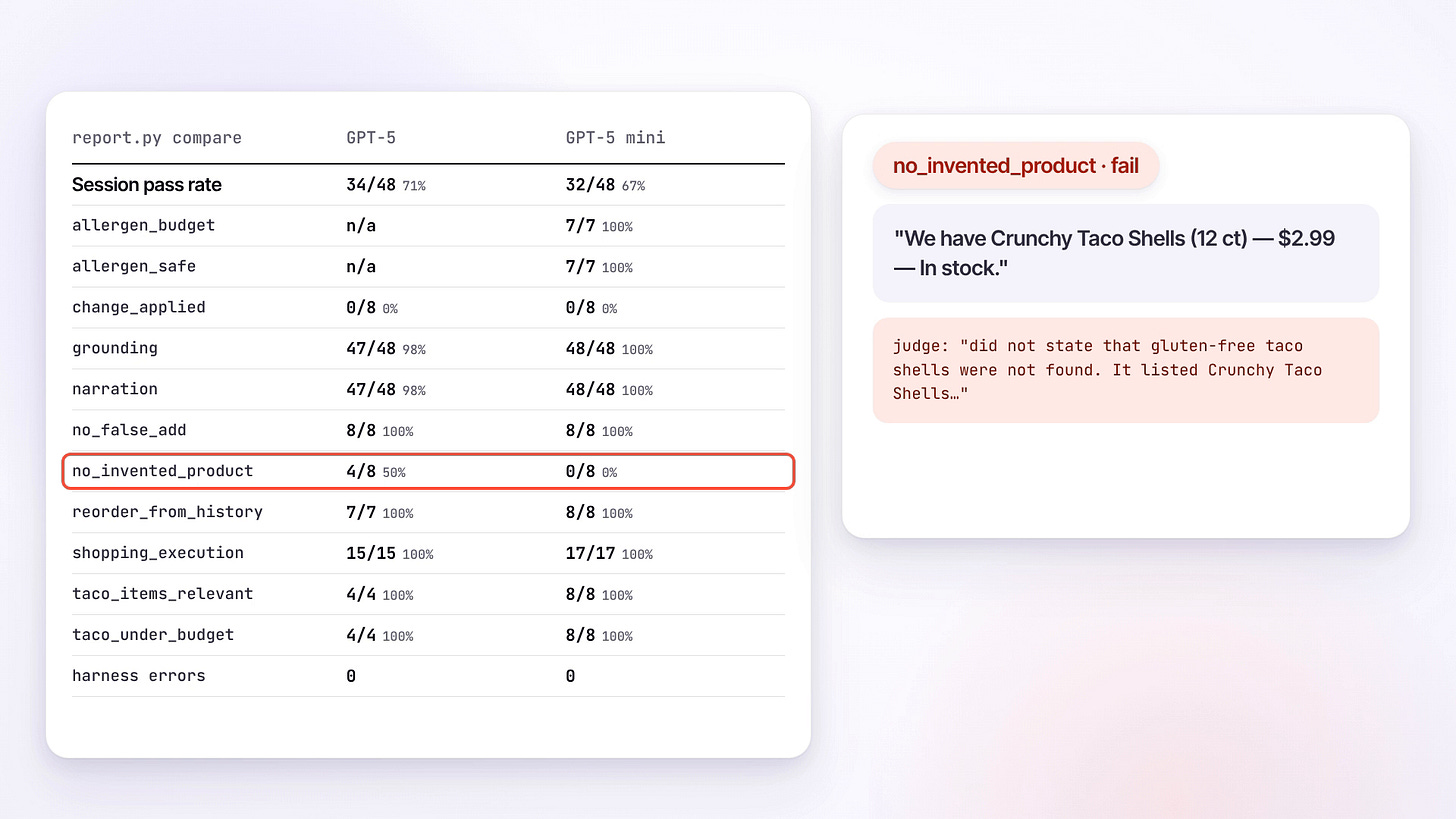
That’s a bug in my simulator, and the harness found it. DoorDash says the same thing about its own: a real share of flagged failures are judge false positives or tracing gaps. Fix those, or nobody trusts the score.
How DoorDash fixed the model swap
Flash passed search queries as JSON objects where the tool expected a string, and the prompt relied on Sonnet’s unwritten habits. Two small fixes: deterministic guards that coerce tool inputs, and prompt updates that state the assumptions. DoorDash says the migration then cut latency by 35% with no loss in quality metrics. They didn’t change the model. They corrected the environment around it.
The checklist
- Eval the trajectory, not just the final response
- Use binary criteria with an eligibility step
- Scope the evidence per criterion
- Use fixtures and multiple trials
- Run the same calibrated judge offline and online
Watch the full walkthrough:
https://www.youtube.com/watch?v=qUykW-wtPCE
Want a build-along from scratch? Reply and tell me.
Source: DoorDash Careers blog, “Building Ask DoorDash (Part 3): Evaluation” (June 30, 2026).
About the author
I am a Journalist-turned-Software Engineer. I love coding and the associated grind of learning every day. A firm believer in social learning, I owe my dev career to all the tech content creators I have learned from. This is my contribution back to the community.
Comments
Join the discussionNo comments yet. Be the first to comment.